New to world models? Our open primer at enterpriseworldmodel.ai explains the concepts these papers build on.
01
WOMO LABS RESEARCH · FOUNDATIONS · JUNE 2026FLAGSHIP01
The Enterprise World Model
We introduce WOMO, a continuously learning causal model of an enterprise's market environment, built from 194K canonical entities and 119K validated causal edges. Unlike sequence models trained on static corpora, WOMO maintains a governed, auditable representation that updates as the world changes. We show that grounding strategic queries in an explicit world model reduces hallucinated causal claims by an order of magnitude relative to frontier LLMs.
Evaluation protocol described in the paper; full text under briefing.
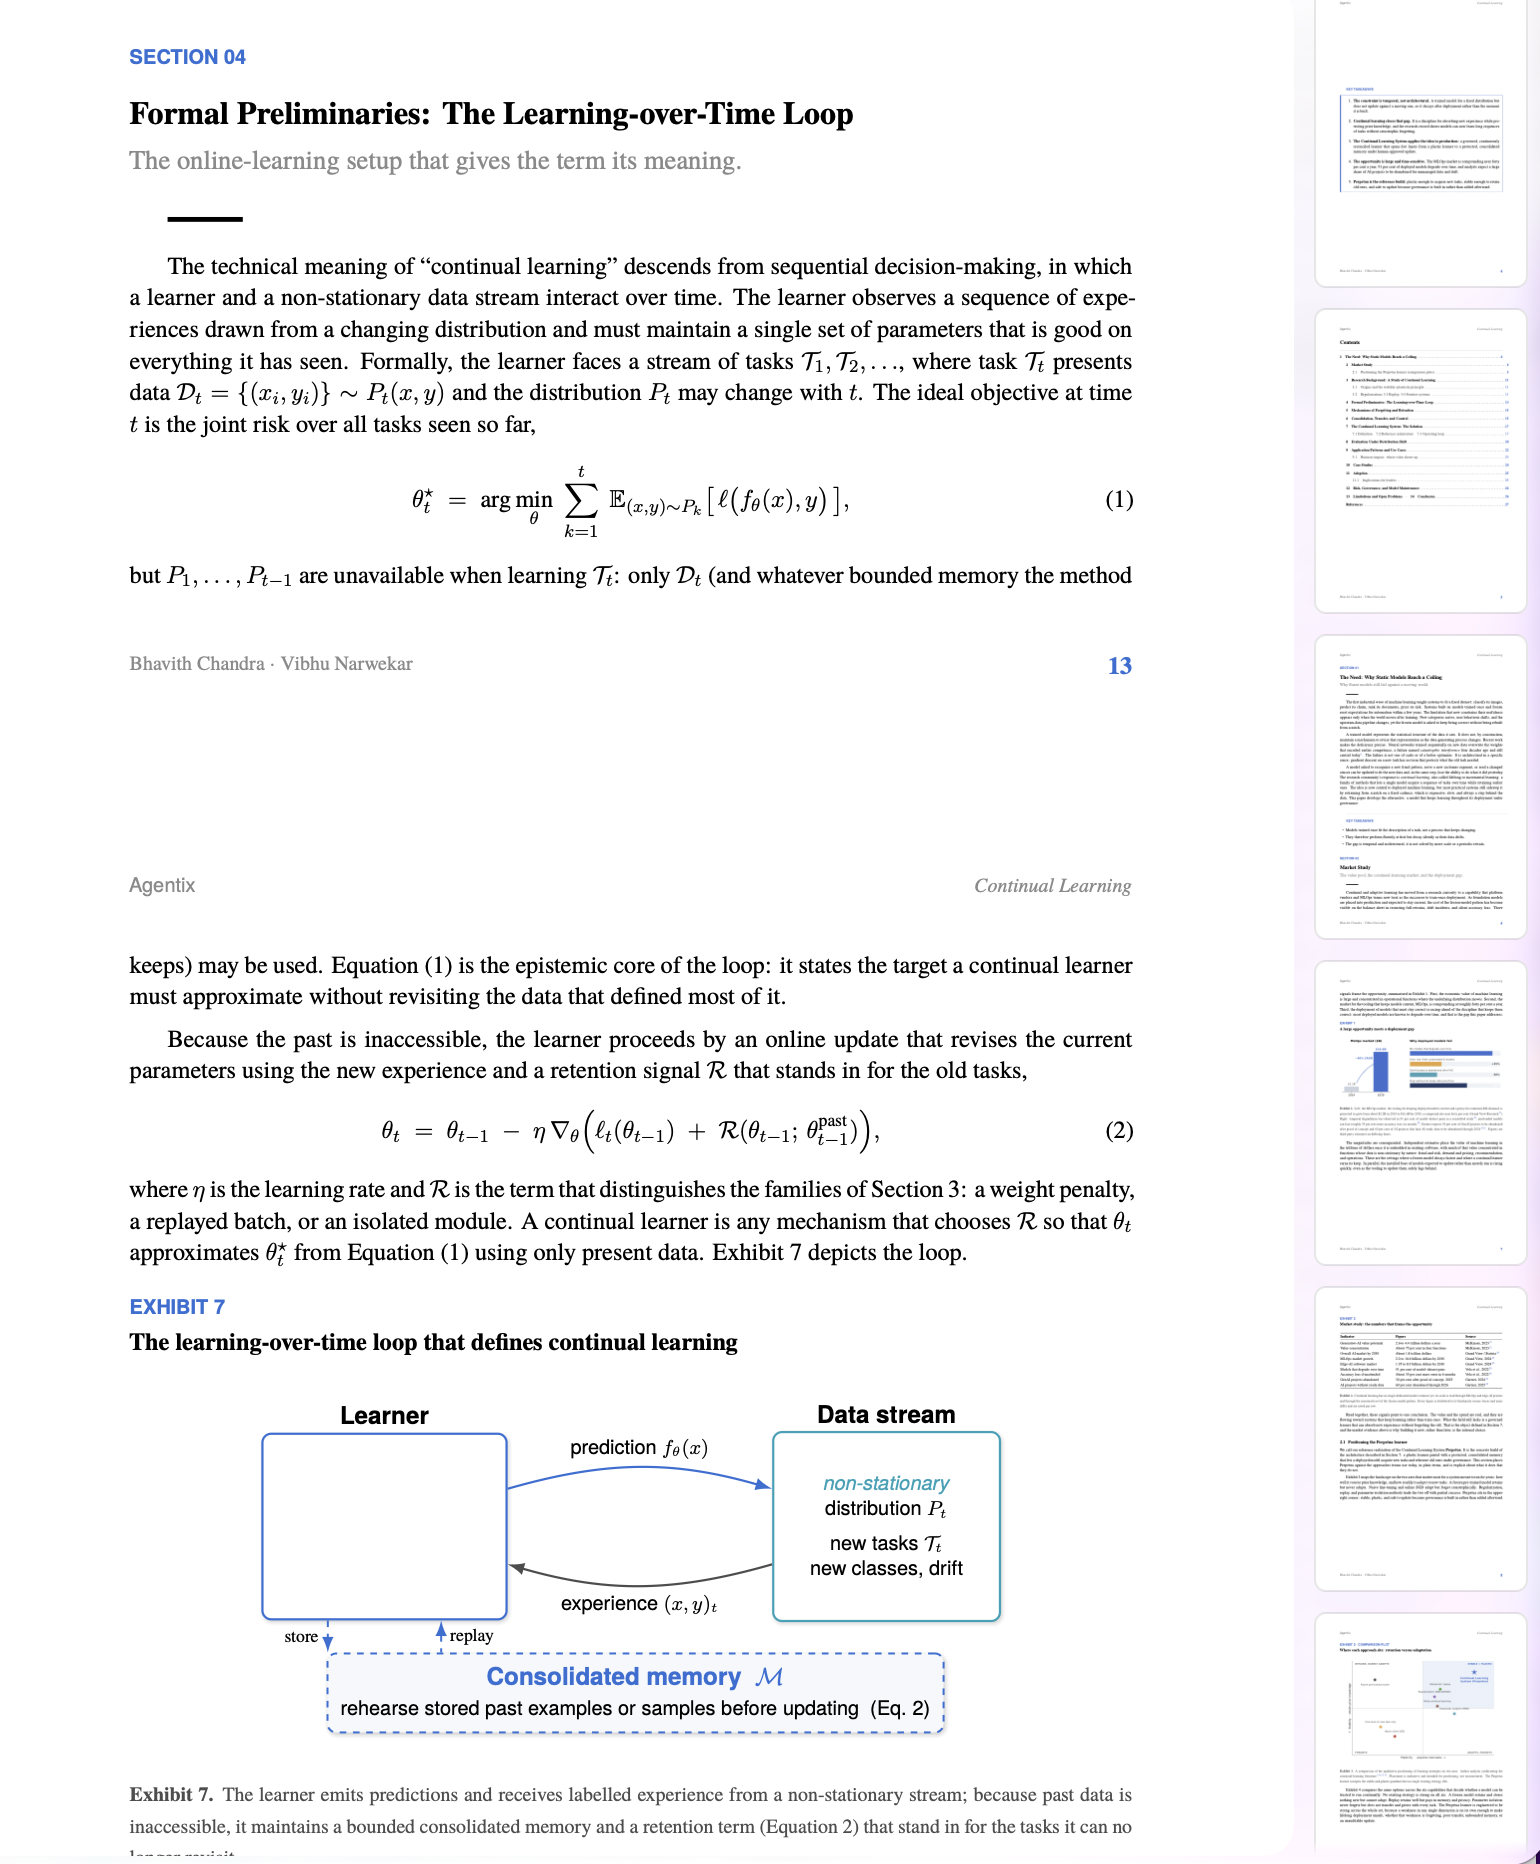
Enterprise models must learn daily without erasing what they knew. We present a consolidation architecture that achieves backward transfer of approximately 0% across 14 months of live market updates. The method requires no replay of raw customer data, preserving the zero-egress deployment contract.
Measurement protocol described in the paper; full text under briefing.
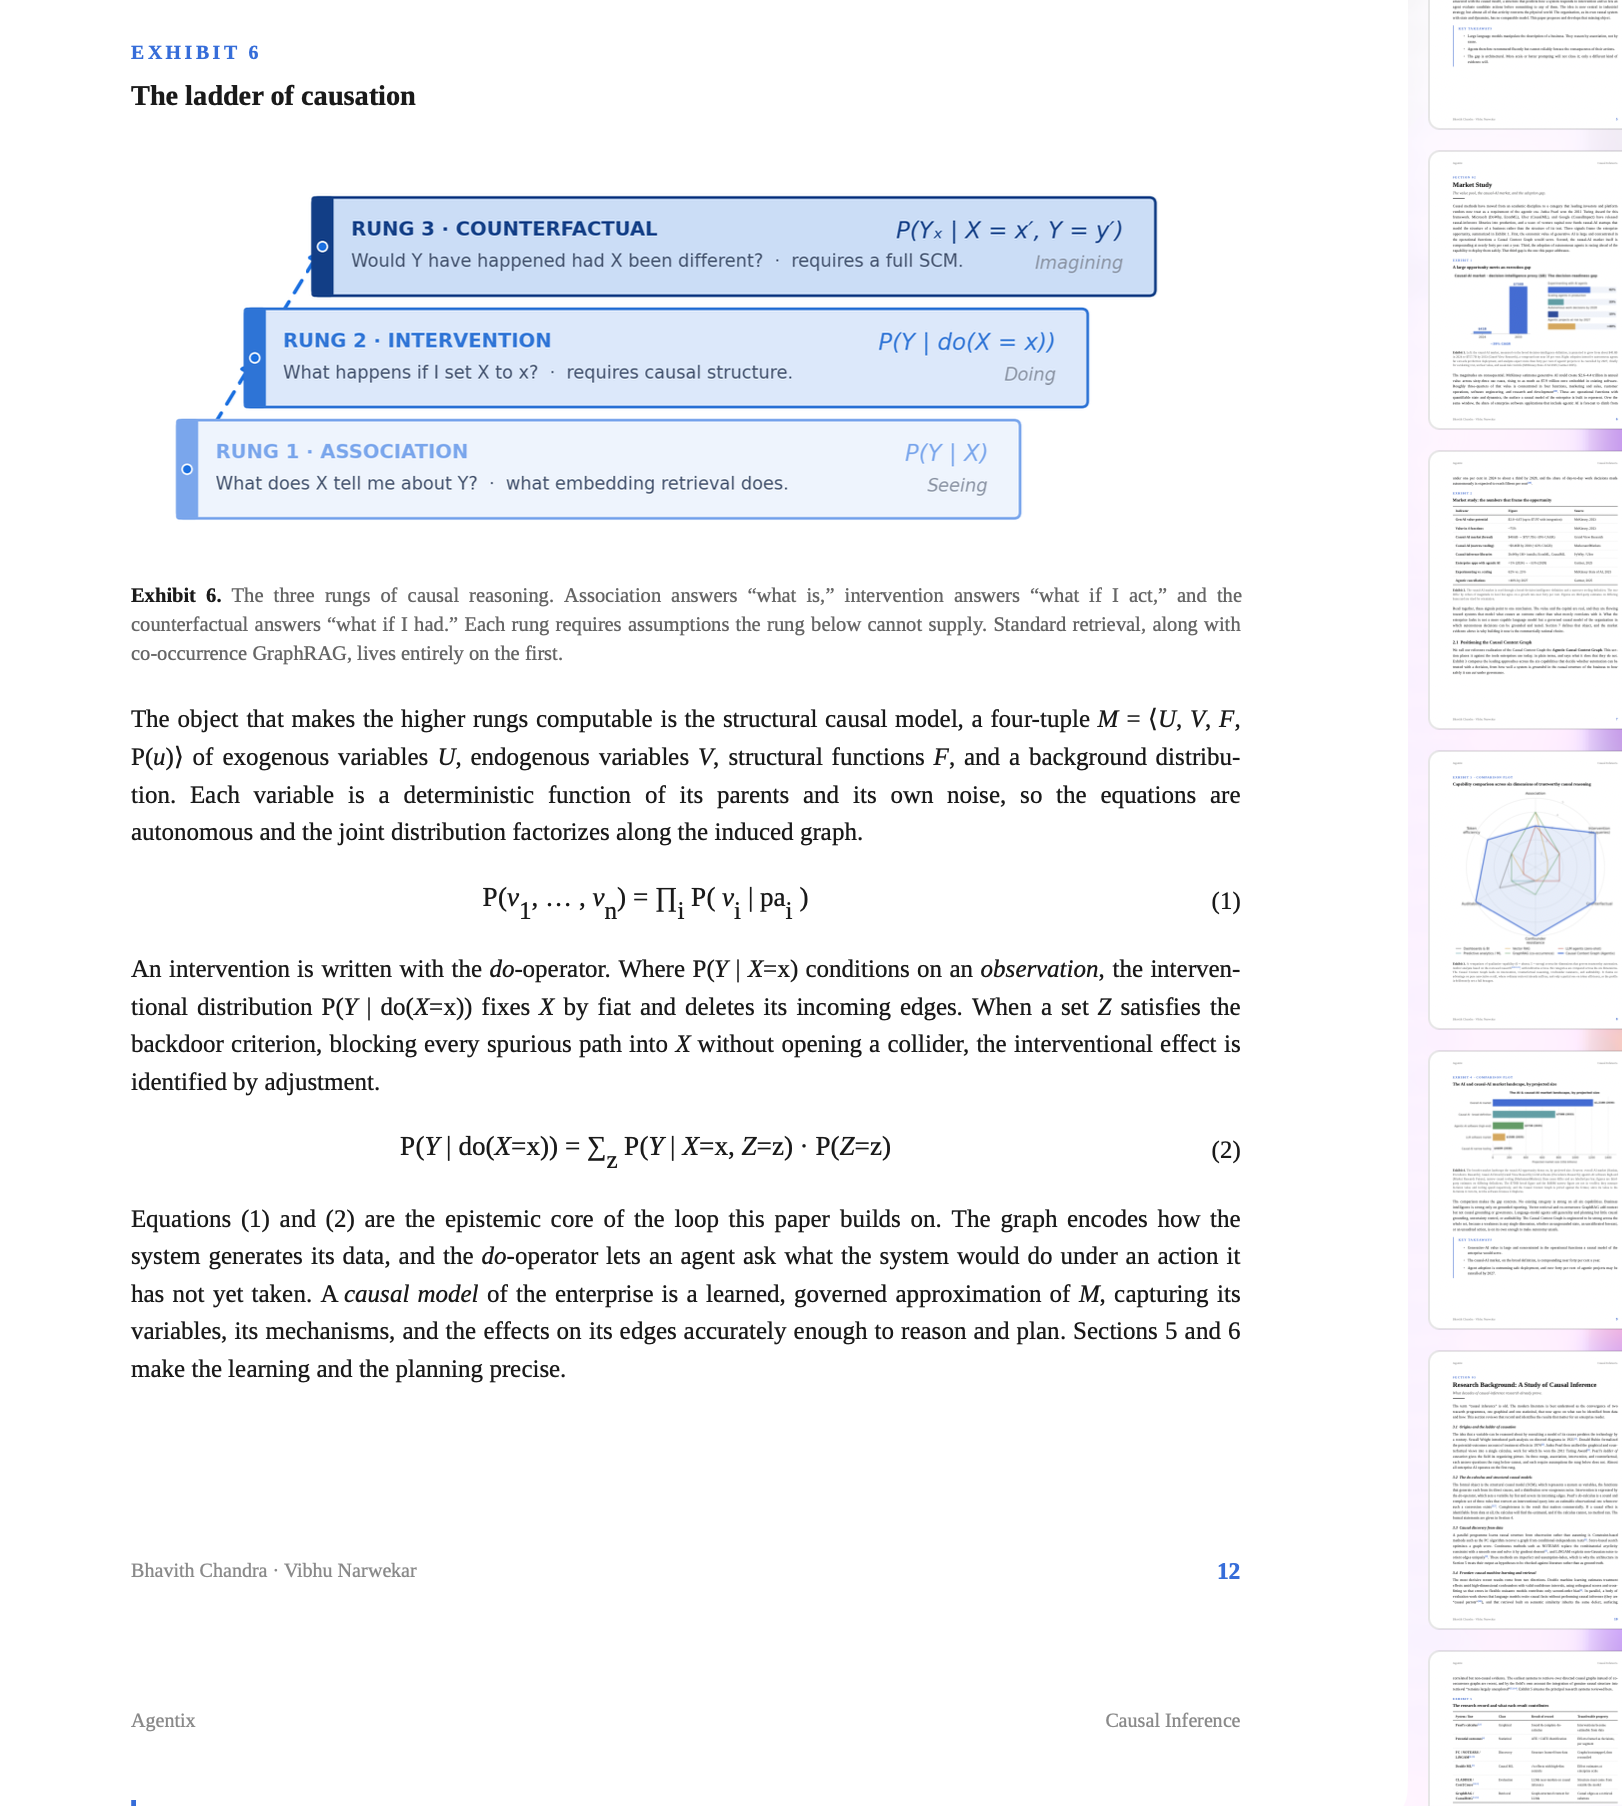
We operationalize Pearl's do-calculus over a 119K-edge causal graph, answering interventional and counterfactual queries in under 150 ms. Identification is checked mechanically before any estimate is returned, so unanswerable queries fail loudly rather than plausibly. We report calibration against 4,100 held-out natural experiments.
Calibration protocol described in the paper; full text under briefing.
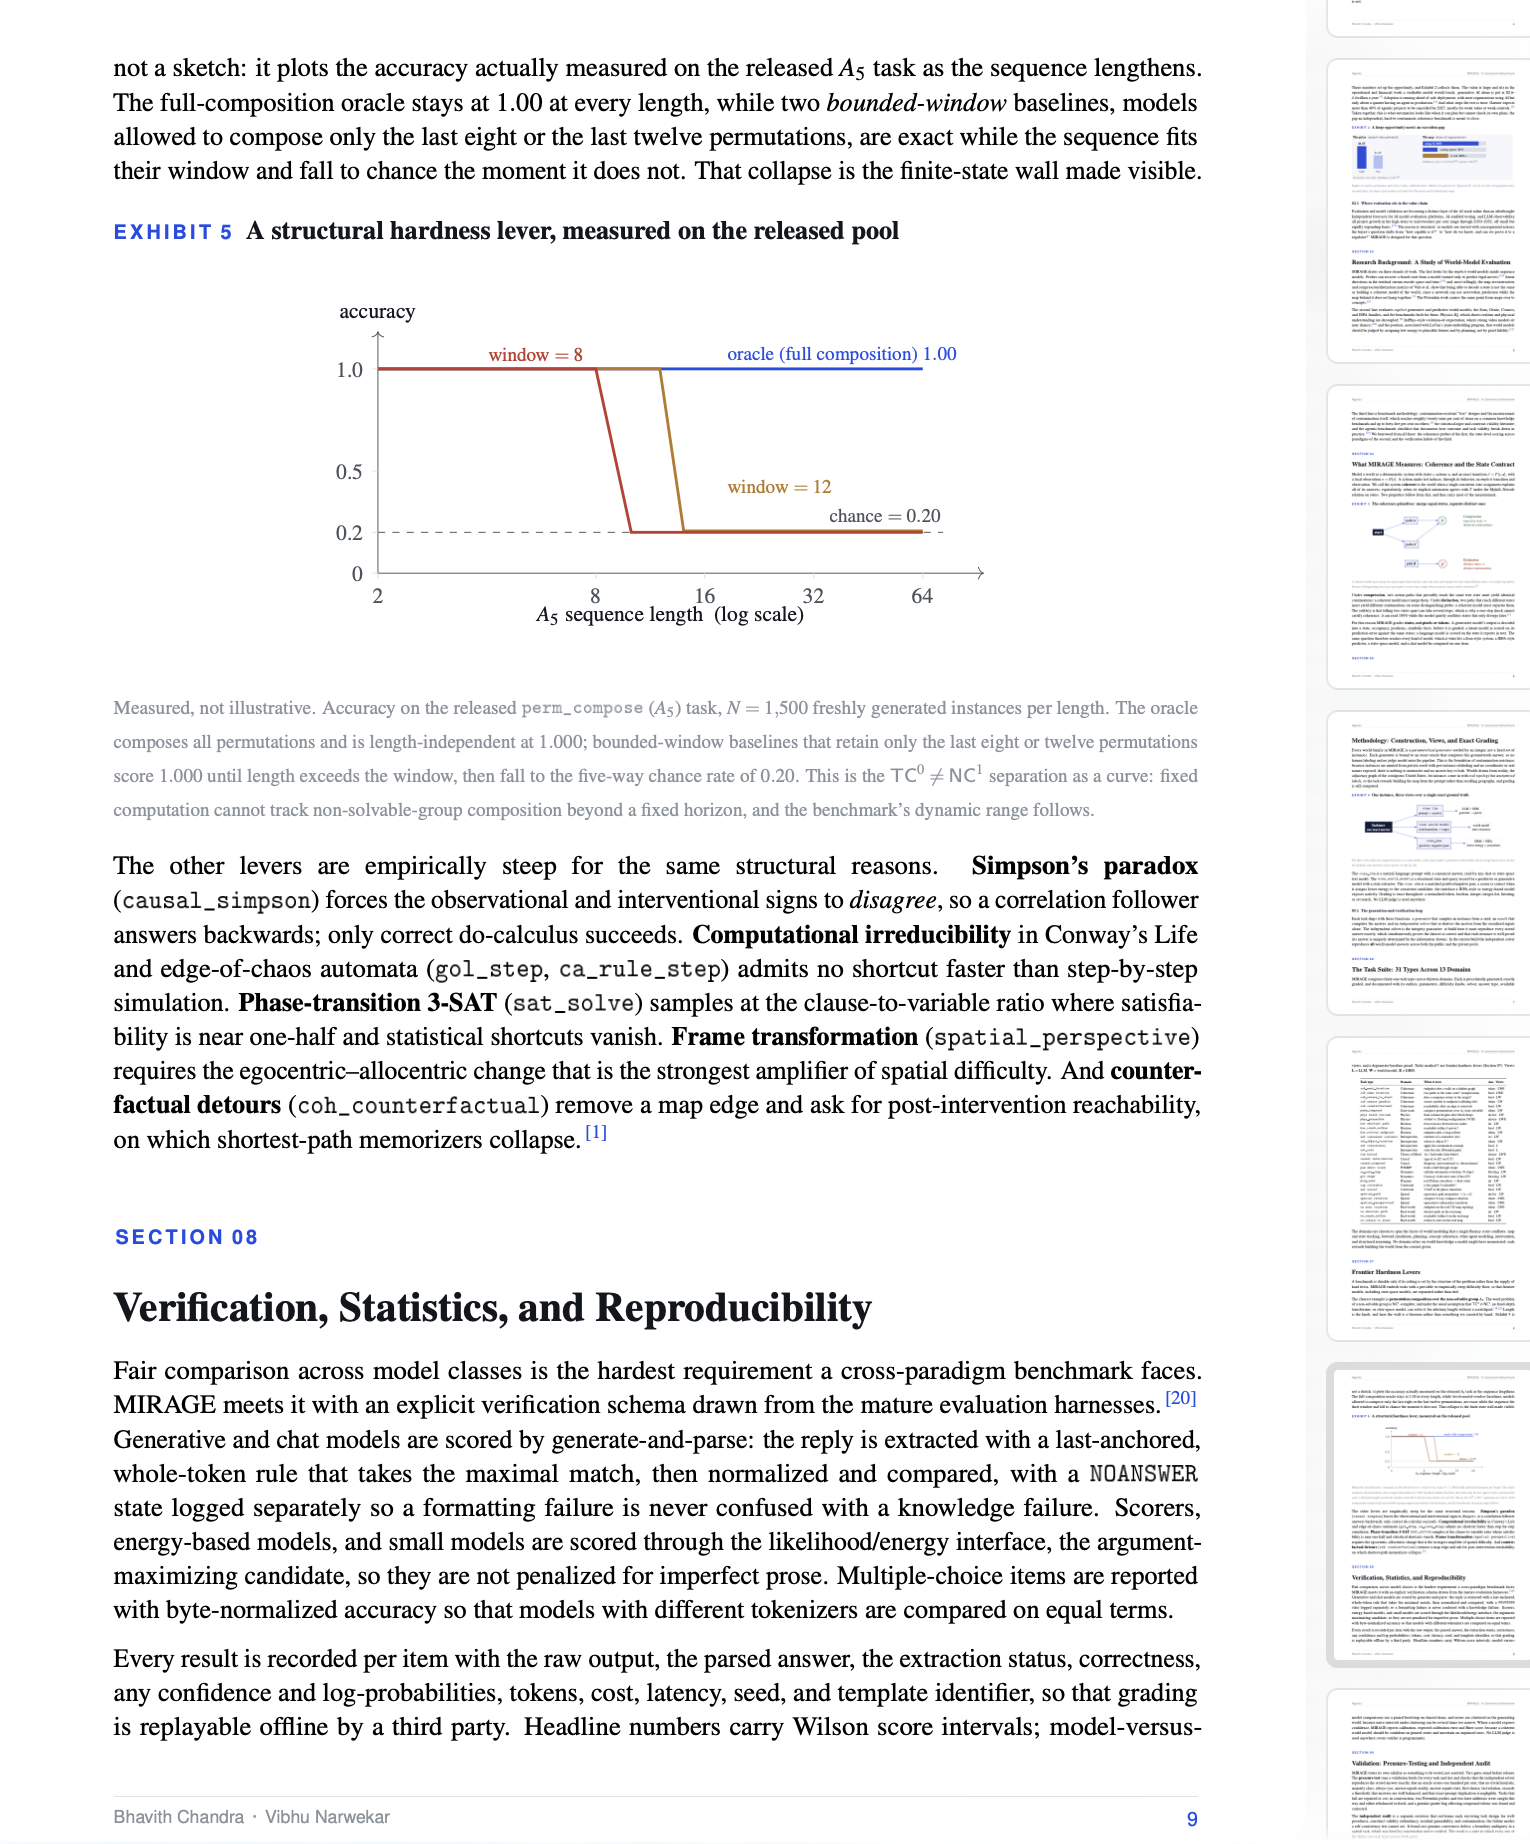
Existing benchmarks grade how convincing output looks; MIRAGE measures coherence: whether a system holds one consistent internal world, a state that moves under rules and reacts to intervention, rather than a fluent description of one. Thirty-one task types across thirteen domains, procedurally generated from private seeds. Answers are computed by a simulator and independently re-derived by a separate solver, so no model and no judge sits in the grading loop, and there is nothing to memorize. Because it grades states rather than text or pixels, language models, state-space models, generative world models, and energy-based scorers are measured on the same items.